AI QA and LLM Evaluation Services for measured quality in variable outputs.
We build datasets, calibrated graders and release checks for AI features. Our AI QA and LLM evaluation services apply quality assurance to variable output: evals measure results against defined criteria, giving your team measured quality for release decisions.
- 120+Projects delivered across 12 countries since 2012
- 100+Senior in-house engineers, six countries
- 5.0Unified rating across 61 client reviews on Clutch
- ISTQBISTQB-certified QA engineers
- ISO 9001Certified quality management, audited by Quay Audit UK
01Overview
Scope the evaluation around your release decisions
We assess the AI feature and existing tests, including independent QA of the surrounding product. Your engineering and domain leads help define the release decisions, representative cases and criteria the evaluation should support.
- Experience operating AI productsWe operate AI products of our own. That experience informs evaluation planning around model changes, processing dependencies, quality review and cost.
- Independent review with your expertsYour feature authors bring useful context and checks. We add a separate engineering perspective and work with domain reviewers to define criteria and examine the results.
- Calibrated gradingA grader scores an aspect of performance using rules, human review or a model applying a rubric. Calibration compares its judgments with your experts' judgments and records where they disagree.
- Related quality servicesQA and test automation covers application behavior, AI integration builds the feature, and penetration testing provides a dedicated security-testing engagement.
02Proof
Independent QA and experience operating AI
Our independent product QA and owned AI products inform the test design and operating decisions in an evaluation engagement.
- Open Room Inc. commissioned independent product QAOpen Room built its image- and document-processing website in-house, then hired us for independent QA. We established the testing workflow, tailored test cases and automation, and produced QA documentation and a Testing Roadmap. Jonathan Muller reported improving development quality and less stressful releases.4things Open Room obtained: well-structured QA documentation, a QA workflow that reflects the product's specifics and the team's capacity, QA Automation with a tailored Test Cases System, and a Testing Roadmap that can be applied at every stage of development
- Owned conversation products with operating experienceWe build and operate Snaplore for meeting knowledge and Talkmetry for HubSpot call intelligence. Both are owned, revenue-generating products; Snaplore has active users.Up to 60%less time on documentation, reported by Snaplore's clients
- Measured search and internal workflow resultsmeinUnterricht's search work measured search success through a controlled experiment. In our internal agent proof of concept, the agent identified late time logs and notified team members and managers through Google Chat. The logging result belongs to that internal workflow.30%improvement in timely work-time logging compliance across unicrew's own team, from an internal proof of concept
03Compare
Who should own your AI evals?
Choose who will define, maintain and act on the quality signal. Internal ownership, an independent engineering partner and platform tooling can each support the evaluation programme.
| An independent QA partnerunicrew | Your own engineersIn-house | An eval or observability platformTooling |
|---|---|---|
| Best forA focused assessment or suite implementation that adds independent review and engineering to your team's quality work. | Best forA team with domain knowledge, evaluation skills and time to maintain the suite alongside feature development. | Best forA team seeking supported tracing, grading runs and dashboards within a platform that fits its stack and data requirements. |
| What it asks of youRepresentative data, domain reviewers, acceptance criteria and decisions on release gates and operating responsibility. | What it asks of youEngineering time, domain review, calibration and a named owner for dataset updates and release decisions. | What it asks of youChoosing criteria and cases, validating grader quality, checking platform terms and assigning someone to act on results. |
| You end up owningThe agreed dataset, graders, thresholds and integration artifacts, with calibration, handover and data or licence rights defined. | You end up owningAn internally maintained suite and the knowledge, review process and release responsibilities behind it. | You end up owningA configured evaluation programme and its supported artifacts, subject to platform access, export and subscription terms. |
Quick self-check
Tick what is true for you. The read-out updates as you go.
0 of 4 true
Scope evaluation for the feature's stage
Evaluation can inform a prototype as well as a live feature. AI integration covers feature implementation; test automation covers deterministic conditions and application behavior alongside evals.
Talk it throughAssess the flow behind the result
Identify the task and the quality concern, then select representative cases and criteria. A focused evaluation can investigate that flow and establish what broader coverage would need.
Talk it throughDefine criteria and release decisions
We work with your domain reviewers to define correct results, meaningful failure categories and release thresholds. That establishes the scope for the dataset, grading and integration work.
Book a discovery callPlan the dataset and grading
Map the representative inputs and known failures, then choose rule-based, human or model grading for each criterion. Calibration shows how grader judgments compare with the domain experts' judgments.
Book a discovery callConnect the quality signal to releases
Define which changes run the suite, what can block a release and who reviews the results. We can add independent evaluation engineering while your team owns the product and release decisions.
Talk about the criteriaFor an AI feature that answers differently every time, we build a set of cases it must get right. The suite runs on every change, and its results show the team what to fix.
 Andrii BurdaSenior Engineering Manager, unicrew
04Capabilities
What we test
Retrieval can find the right material while generation invents. An agent can reach the right answer through actions outside its intended workflow. We assess these dimensions separately to guide fixes and release decisions.
- LLM evaluation services
LLM feature evals
Accuracy, groundedness, formatWe score outputs against accuracy, groundedness and format criteria on agreed cases. Repeated trials help assess variable output; comparisons across prompt or model versions provide a regression signal.
- RAG evaluation
RAG quality
Retrieval scored apart from generationWe assess retrieval quality separately from the generated answer. Cases test whether the right material is retrieved and whether the answer is supported by it, helping identify chunking, index and generation issues.
- AI agent testing
Agent behavior testing
The path, not just the destinationWe evaluate tool calls, traces and task outcomes against the intended workflow. Cases can test the selected actions, path and recovery behavior, with the criteria defined for the agent's job.
- MCP server testing
Tool and MCP server testing
Auth boundary and malformed inputWe test the tools exposed to the agent, expected inputs and malformed-input cases. We check the selected authorization and credential boundaries against the server's transport and deployment configuration.
- AI security testing
Safety and AI application security
Prompt injection and jailbreaksWe assess prompt injection, data leakage and jailbreak behavior on selected cases, including tool inputs and retrieved documents. We record the outcomes against agreed security criteria and route findings for review.
- LLM observability and monitoring
Observability and drift monitoring
Quality drift and spendWe connect traces and metrics to the quality and spend signals your team needs to review. Monitoring tracks drift and changes in usage, with alert, investigation and dataset-update responsibilities defined for the operating scope.
- QA for AI applications
Classic QA foundation
ISTQB-certified engineersWe test APIs, UI, data flows, integrations and permissions alongside the model's task quality. Conventional checks cover schemas, invariants and deterministic conditions. unicrew has ISTQB-certified QA engineers.
05Trust
A repeatable suite for release decisions
The suite turns agreed criteria and finite cases into a repeatable release signal, with handover and CI integration defined for your stack, data rights and licences.
- DefinedWhat good means, written down in numbersThe criteria, the thresholds, and which failures are release-blocking
- Yours to rerunThe dataset, the graders and the suiteHanded over with the calibration, so you are not renting your own quality signal
- In your CIA gate on every prompt and model changeA regression caught on the pull request rather than by your users
06Stack
Evaluation connected to your application stack
We design evaluation around your model endpoints, data stores and CI. TestCafe comes from our independent product-QA automation work; the model and orchestration checks follow the feature's actual stack.
 Python
 LangChain
 AWS Bedrock
 OpenAI / ChatGPT
- Whisper AI
 TestCafe
07Engagement
Choose the evaluation engagement
Commission a defined suite, embed evaluation engineering in your team or assign continuing QA work. The engagement sets the scope and operating responsibilities.
Independent QA and eval consultancy
Start hereWe define criteria with your reviewers and build the dataset, graders and suite. The agreed handover includes calibration and the release-integration artifacts, with data rights and licences recorded. There is no minimum engagement period.
- Best when
- The team that built the feature is the only team judging it
- You pay
- Outcome based, quoted per project
- Typical start
- Two to four weeks
An embedded engineer or QA pair
Embedded pairWe work inside your team to develop and maintain evaluations alongside your engineers. Your product and domain owners set priorities and acceptance; we define review and knowledge-handover responsibilities for the engagement.
- Best when
- Evals are ongoing work, not a one-off project
- You pay
- Billed monthly, per team member
- Typical start
- Two to four weeks
Ongoing QA ownership
Long-runWe maintain the suite, add cases and review drift and cost in production. The remit can include conventional testing around the model, with responsibilities for release checks, monitoring and escalation assigned between our team and yours.
- Best when
- You want one partner accountable for AI and classic QA together
- You pay
- Billed hourly, quoted per project
- Typical start
- Two to four weeks
Review the evaluation suite you already run
We assess case coverage, grader agreement and the connection between scores and release decisions. The review identifies useful checks, gaps and options for adapting or rebuilding the suite against your feature's requirements.
08Industries
Quality criteria for the domain task
Domain reviewers connect the quality criteria to the decisions people make with the feature. We turn those requirements into cases and grading rules.
Logistics and transportation
Test inventory, dispatch and inspection outputs against incomplete or conflicting field data. Define correct extraction and the decisions it supports in vehicle-inspection workflows.
Hospitality and leisure
Evaluate booking, ticketing and venue features against the expected output, response time and cost criteria. Relate the test cases to the platform workflow and the usage the team needs to support.
Real estate
Evaluate summaries and extracted fields against property records and negotiation threads. Combine those checks with independent application QA, including the browser and permissions workflows around the feature.
EdTech and learning
Assess search relevance and retrieval separately from generated answers. The linked search and AI engineering work used a controlled experiment to measure search success across relevance, filtering, autosuggest, tagging and embeddings work.
Fintech
Check figures and explanations against the financial records that support them. Domain reviewers define grounding, format and escalation criteria for the accounting or payment workflow.
Healthcare
Define accuracy, safety and refusal criteria with the people responsible for the clinical use. Test the selected cases and connect findings to human review and the monitoring or integration workflow.
Name the AI feature you need to trust in production
Bring the feature, the decisions it supports and the quality questions your team needs to answer. We discuss criteria, available cases and how evaluation should connect to releases.
What happens after you contact us
- We reply within one business dayWe respond to your enquiry and arrange the next conversation about evaluation scope.
- A call about which failures are expensiveWe discuss the feature, its users and which quality failures matter to the decisions it supports.
- A written definition of doneWe define the criteria, proposed release thresholds, data requirements and review responsibilities.
- Contracts and NDAs, then a start dateWe settle the contracts, NDAs and data access for the work. Most engagements start within two to four weeks.
09Delivery
From criteria to a working release signal
We connect your quality criteria to a repeatable suite and the agreed release and monitoring workflow. Your domain experts and engineering owners approve the decisions at each stage.
- Define what good meansWe define accuracy, groundedness, tone and safety criteria for the task with your reviewers. Your product and domain owners identify important failures, approve examples and decide which thresholds should block a release.You getA written definition of done: the criteria, the thresholds, and which failures are release-blocking.
- Build the dataset from real inputsWe assemble representative inputs, edge cases and known failures, then version and label the dataset. Your team supplies authorized production-like data and helps review labels, with access, handling and retention defined for the work.You getA versioned dataset drawn from your real inputs, with edge cases and known failures labeled.
- Calibrate the gradersWe select rule-based checks, human review or model rubrics for each criterion and compare judgments with expert-reviewed examples. Your domain reviewers resolve disagreements; we document the measured agreement and grading limits.You getGraders whose agreement with human judgment is measured and written down, not assumed.
- Gate releases in CIWe wire the suite into the CI pipeline in scope and configure the agreed release gates. Your CI owner provides access and defines the changes that trigger checks, the thresholds that block a release and who can approve an exception.You getThe eval suite wired into your CI with a threshold on every change, plus the runbook for when it fails.
- Monitor drift and cost in productionWe implement the agreed quality and cost monitoring, then review findings for dataset updates. Your operating owner confirms where traces may be stored, who investigates alerts and how new cases and grading changes are approved.You getProduction monitoring for quality drift and spend, and a loop that feeds real failures back into the dataset.
10Client voices
Client reviews of QA and engineering work
Artelogic’s work had a very positive impact on our team’s morale. As our development quality was improving, our engineers were more confident in what they were doing, allowing them to work faster and with more confidence. As a result, our releases took less time and were less stressful.
Our headline result was a controlled experiment showing a roughly 9 percent lift in search success rate. The features built are live in production, and the AI tagging and embeddings work set up our move to vector search. What stands out most is their ability to own work end to end, from user-facing search features to the AI and data layer underneath.
We were able to get the work completed in the expected time frame. There were little to no defects which was very nice because it allowed us to release and move on to our next project without having to back peddle. They were very accessible and took the time to understand our needs. They truly felt like part of the team.
We have had six out of seven on time and on budget project executions. Each engagement was a minimum of six months of effort. They had a flexibility and willingness to adapt their processes to match my requirements both on communication and the development processes. I never had a problem with any of their code from a code quality perspective.
Site was migrated and re-written, the new system is much more stable, and performance highly improved. Excellent technological level. highly responsive and communicative. They are highly committed to the project and business goals.
11Case studies
Our case studies
Snaplore is our owned meeting-intelligence product. The automation study covers unicrew's internal proof of concept. Client reviews naming Artelogic refer to unicrew under our former brand.
See all case studies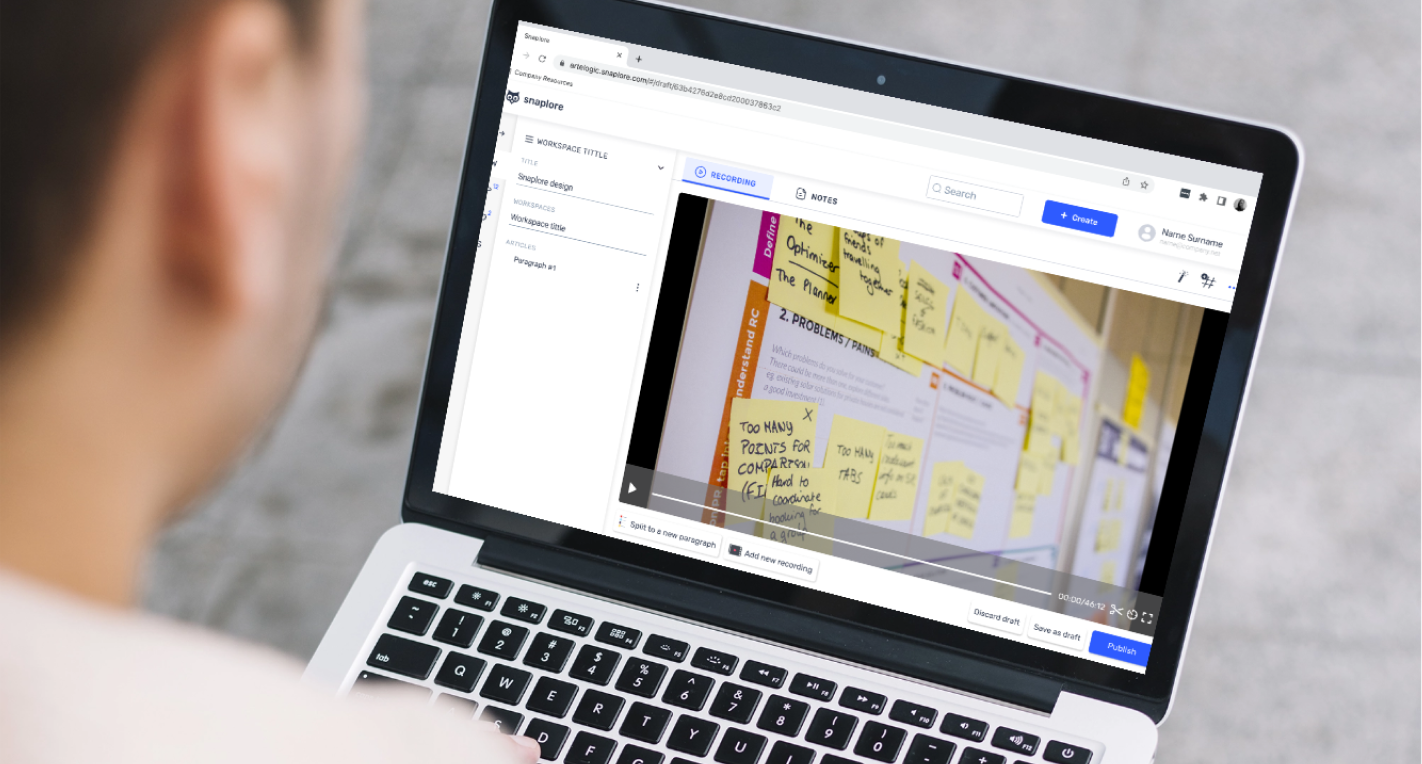 Built by unicrewAI-powered knowledge managementSnaplore is unicrew's own product, built and operated in-house. It uses AI to transform how organizations document, structure, and share information, making meetings, training, and project discussions instantly accessible and actionable.Up to 60%Less time on documentation
 Built by unicrewAI-Powered Automation for Project ManagementAn AI bot that enhances operational efficiency by automating a time-consuming internal administrative task.30%Improvement in timely work-time logging compliance
12Questions
Questions about AI QA and LLM evaluation
Some AI outputs can vary while remaining valid, so one exact expected answer may be too narrow a test. Evals assess semantic and task quality against criteria that allow valid variation.
Classic quality assurance continues to test APIs, permissions, schemas, invariants and deterministic conditions. We combine those checks with evaluations of the model's output, using the quality criteria and release gates appropriate to the feature.
An LLM eval tests a language-model task against defined criteria to provide measured quality on selected cases. A case defines the input and success criteria; repeated trials help assess variable output.
Graders score aspects of performance using code, human review or a model applying a rubric. Calibration compares grader judgments with expert judgments. The suite provides a regression signal for the cases tested, with traces and task outcomes available for more complex workflows.
The suite connects representative cases to grading criteria and release decisions.
- A versioned dataset with representative inputs, edge cases and known failures.
- Calibrated graders and the record of their agreement with domain reviewers.
- Quality thresholds and the failures defined as release-blocking.
- CI gates, result reporting and a runbook for reviewing failures, as scoped for your stack.
RAG evaluation separates retrieval quality from generation quality. Monitoring for drift and cost can extend the suite into the agreed operating workflow.
Yes. We scope agent evaluations around the intended task, tool calls, traces and actual outcomes. The path matters alongside the final answer when a workflow involves several actions.
Cases can assess action selection, tool inputs, recovery behavior and prompt-injection attempts at the selected boundaries. We agree the criteria and review the observed results. Passing a finite suite supplies evidence on those cases; it does not establish that every future action will be correct or safe.
We quote against the scoped dataset, grading and integration work. The main cost drivers are:
- The tasks and quality criteria to cover.
- Data availability, assembly and labeling.
- Rule-based checks, human review and model-grader calibration.
- Integration with the feature, data stores and CI.
The billing model follows the engagement:
- Fixed price: outcome based, quoted per project.
- Time and materials: billed hourly, quoted per project.
- Team extension: billed monthly per team member.
The schedule follows the data, criteria, grading and CI work in scope. We assess those dependencies during discovery and produce the implementation plan and estimate.
Your reviewers need to approve the criteria and calibration; your CI owner needs to confirm access, triggers and release-blocking behavior. Existing datasets and checks can inform the plan, while a prototype can begin with a focused task and representative cases. There is no standard duration for every suite.
We design the suite for the model endpoints, data stores and CI pipeline in scope. Integration depends on available interfaces, permissions and the processing terms for your data.
We agree where cases run, where traces and results are stored and how your release or observability tools consume them. For an agent using tools, MCP server work is a related implementation boundary; the evaluation scope identifies which tool behavior and configuration to test.
Evaluations can support applicable engineering evidence under the EU AI Act; an eval suite alone does not establish compliance. Duties depend on the system's use, risk category and your role, with exceptions and staged application of requirements.
Your legal and domain owners identify the obligations that apply. We scope criteria, repeatable tests, results and review records to support that evidence. Oversight, security testing and documentation requirements are defined for the relevant system rather than assumed identical for every EU-facing organization.
Compare the evaluation design, its integration into decisions and what your team can maintain afterwards.
- Review the proposed cases, criteria and grader calibration against domain judgments.
- Confirm release integration, monitoring scope and who investigates findings.
- Agree dataset, suite and calibration handover, including data rights and platform licences.
- Check relevant project evidence and organizational credentials against their actual scope.
unicrew is ISO 27001:2022 and ISO 9001:2015 certified, renewed through a multi-stage audit with Quay Audit UK, and has ISTQB-certified QA engineers.
It fits when an LLM, RAG or agent feature needs measured evidence for a product or release decision. Evaluation can start with a scoped prototype and mature with usage and risk, including features already in production.
Related work can complement the suite:
- QA and test automation checks deterministic conditions and application behavior.
- AI and ML development builds or adapts models that the suite can evaluate.
- An AI-readiness assessment addresses the data and implementation prerequisites.
For programme planning, see our enterprise AI roadmap.