
AI development services from a team that runs AI in production
AI development services cover everything between deciding which AI use case is worth funding and keeping the answers good once real users depend on them. Seven services do that here, and this page tells you which one is yours.
01Work
Why most AI pilots die between the demo and the customer
Four failures, and not one of them is model quality. Each is settled in the design, which is why a better model so rarely rescues a stalled pilot.
Nobody defined what correct means
A system that answers differently every time cannot pass a pass/fail test, so without a scored, repeatable measure of correct, the launch decision comes down to whether the last demo went well. That measure is also what turns next year's model upgrade into a decision rather than a gamble, and building it is a service of its own: AI QA and evals, which sits in the quality category rather than this one.
The data underneath was never ready
Retrieval returns the wrong document and the model writes confidently around the gap. That is a data engineering problem wearing an AI costume, and no model choice fixes it: the best answer available is bounded by what the search layer underneath can actually find.
The cost curve was discovered in production
Per-token pricing behaves nothing like a server bill: a feature that is fine in a pilot of fifty users is a budget conversation at fifty thousand. Caching, routing and the choice of model are design decisions, and they cost far more to retrofit than to make.
The attack surface was assumed, not tested
Prompt injection, data leaking through context and model access controls are a new class of exposure sitting on top of the ordinary kind, and conventional testing was not built to find them. The useful thing about that class is that it is testable, which is security work rather than an assumption that the model is a box nobody can reach through.
02Services
Seven AI services, and which one your problem is
One row per service page. The middle column is doing the work here: it names the condition under which each of these is the right purchase rather than the interesting one.
| Service | What you are actually buying |
|---|---|
| Conversational AI and voice | Speech is the dataThe calls, meetings and voice notes you already record become structured records your own systems can search and act on, instead of files nobody opens. It is the pattern behind both products we run: audio in, transcription, structured output inside the tool people already use.Conversational AI and voiceOr book a meeting |
| AI integration | Your software has usersA hosted model wired into the software, data and workflows your business already runs on, including a search layer over your own documents so answers come from them. This is the row where the thing you are changing already carries users, so the rollout weighs as much as the model.AI integrationOr book a meeting |
| AI and machine learning development | Your records are the edgeA model trained on records only you hold, returning a score, a ranking or a prediction in the place a person decides today. It is the one AI buy that can be measured before it is funded, on cases the model has not been shown.AI and machine learning developmentOr book a meeting |
| AI agent development | It must act, not answerSoftware that takes a goal, plans the steps and carries them out across your tools. An agent that can act can act wrongly, at speed, so the decision you are really making is how far it may go before a person looks, and that line is set one action at a time.AI agent developmentOr book a meeting |
| MCP development | One system, many agentsA Model Context Protocol server publishes a system you already run once, its data and the actions it permits, and every AI client you adopt reaches it through that instead of a connector of its own. Who may do what lives in the server rather than in each agent.MCP developmentOr book a meeting |
| AI consulting | Nothing is funded yetYour candidate use cases ranked against the data you actually hold and the systems that would have to carry them, ending in a written decision about what to fund. That decision is allowed to say not yet, which is why it is worth having before a build rather than after one.AI consultingOr book a meeting |
| Chief AI Officer as a service | It has to stay ownedA senior AI leader on your leadership team part-time, holding the strategy, the governance and the rollout. Every other row here gets decided or built and then finishes; this one is bought on how long somebody stays accountable for it.Chief AI Officer as a serviceOr book a meeting |
03Fit
When we would tell you not to use AI for this
Five of the six rows below end somewhere smaller than the AI build that was asked for. The sixth is the case where we would say yes without hesitating.
| Your situation | What we recommend instead |
|---|---|
| A rules-based process that never varies | Not AIIf the logic can be written down, write it down. Process automation is cheaper, faster, auditable, and it gives the same answer twice. A model here adds cost and removes certainty. |
| The process changes every month and nobody has written it down | Fix the processAn agent placed on top of a process nobody can describe amplifies the confusion and gives it an interface. Whatever the tooling, an undocumented process is the thing to fix first. |
| The data is scattered, undocumented and partly wrong | Data layer firstSearch over messy data produces confident wrong answers, which are worse than no answer because they look like one. Data engineering first: what a model can tell you is capped by what the layer underneath it can find. |
| A regulated decision where a person has to be accountable | Assist, do not decideUse the model to prepare, summarise and surface, and leave the decision with the human whose name is on it. That is a smaller, shippable build; full automation here is a compliance problem you have chosen. |
| A general question a hosted assistant already answers well | Buy, do not buildPay for the product. A thin wrapper over a public model buys you a maintenance burden and a worse copy of something that keeps improving without you, and the gap widens every release. Build only where your own data or your own workflow is the advantage. |
| Calls, meetings or documents holding knowledge nobody can reach | This is the oneThis is the case where we would say yes without hesitating, because it is the one we solved for ourselves twice. Conversational AI and voice. |
Who does the work, and how it is billed
unicrew has been building software since 2012 and is now 100+ senior in-house engineers across six countries, certified to ISO 27001:2022 for information security and to ISO 9001:2015 for quality management, renewed with Quay Audit UK through a multi-stage audit. ISTQB-certified QA sits inside every sprint, on every engagement. There is no minimum engagement period. Billing is time and materials, fixed price, or team extension per team member per month, and most engagements start within two to four weeks.
04Track
We were doing this before it had a category
Four dated points on the public record. Each of the first three is a verified Clutch review.
- 2017: a language problem inside a live accounting systemWe took over a part-built platform for a London financial advisory firm, automated the bookkeeping reconciliation against their invoices, and put encryption and account protection around the financial data. The same brief held a natural-language problem, reading transaction descriptions and acting on what they said, and we proposed the methods for it. It launched that year with around 30 accounts on it.You getVerified Clutch review
- 2020: a recognition system that improved as it ranFor a Munich software company, a web application on AWS that reads incoming data, sorts it into a database table and puts the first result in front of an operator to release or correct. Those corrections feed back into the algorithm, so its recognition rate climbs with use. Two people typing were entering about 5,000 data sets a month; with the component the client reached twice that.You getVerified Clutch review
- 2023: testing an AI platform we had not builtA Japanese real-estate company built a website with image processing and AI to digitise paper documents, did the development in-house, and hired us to test it. There was no documentation, so we explored the product ourselves, from February to November. Output that varies breaks pass and fail, which is the problem AI QA and evals exists to solve.You getVerified Clutch review
- Today: our own products, and yoursSnaplore and Talkmetry run in production on GPT models and AssemblyAI, with Whisper handling speech in Snaplore, and Snaplore has active users. One internal proof of concept on Python, AWS Bedrock and LangChain put an agent on our own team's work-time logging.You getTwo live products
Everyone asks which model to use. In running our own AI products, the model has never been the thing that decided whether a feature was any good. What decided it was whether we could tell, on any given day, that the thing was still working. Build the way you measure it before you build the feature, or you will be shipping on the strength of the last demo you happened to watch.
 Oleksandr TrofimovChief Technology Officer, unicrew
05Proof
Three AI builds with a number attached: two client systems, one product of our own
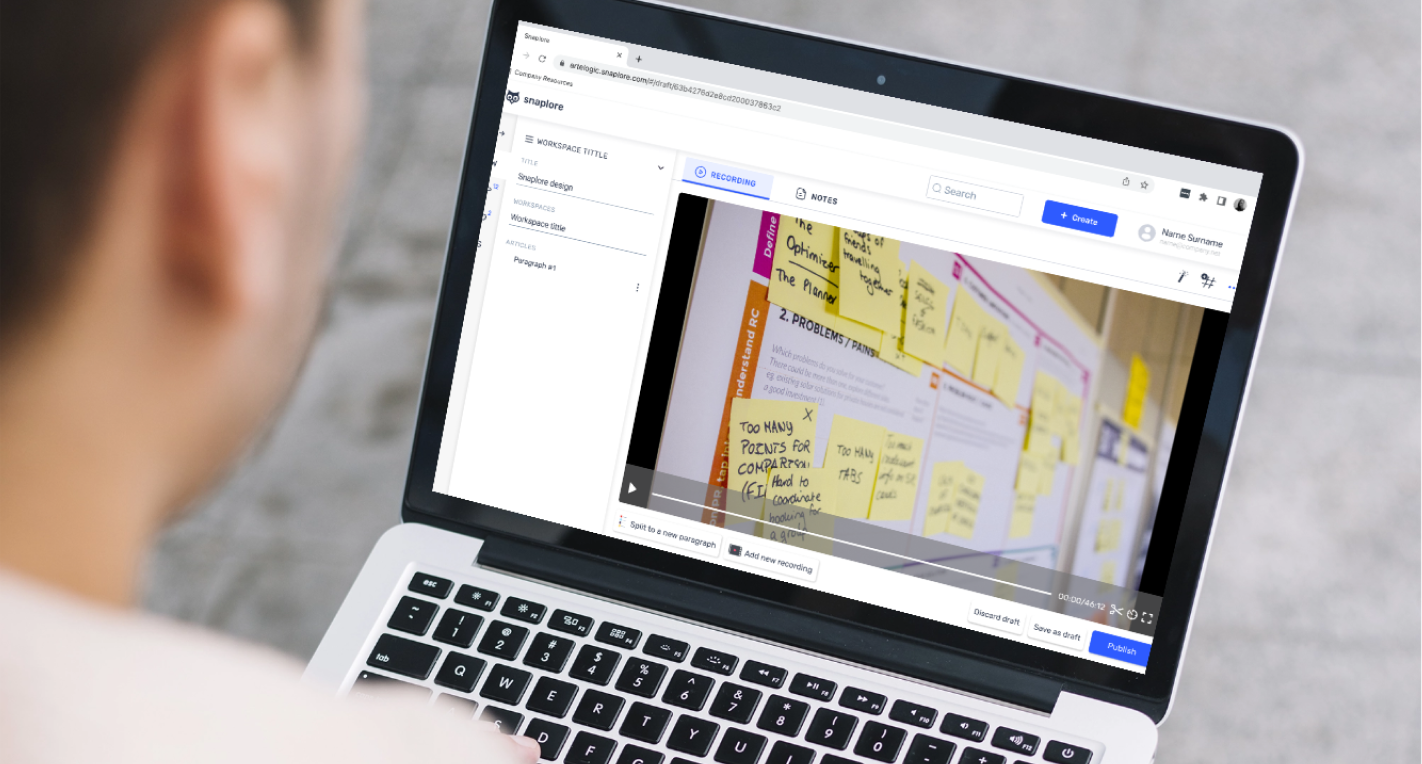 AIRevolutionizing Knowledge Management powered with AISnaplore is unicrew's own product, built and operated in-house. It uses AI to transform how organizations document, structure, and share information, making meetings, training, and project discussions instantly accessible and actionable.Up to 60%Less time on documentation
- AutomationDoubling data-entry throughput with a custom recognition toolunicrew automated a manual data-entry bottleneck with a C# and AWS recognition tool, doubling the data sets the team got through each month.2xData sets processed per month
06Clients
Two clients: one on AI features live in production, one on a domain we had not worked in before
Our headline result was a controlled experiment showing a roughly 9 percent lift in search success rate. The features built are live in production, and the AI tagging and embeddings work set up our move to vector search. What stands out most is their ability to own work end to end, from user-facing search features to the AI and data layer underneath.
Even though Artelogic didn’t have a background in this area, they learned quickly and repurposed technologies they’d used before in order to solve the business problem. I was very impressed with this ability, as most of the people we contacted before implied that they’d need to spend a lot of time of trying to understand our business logic.
07Questions
What teams ask before starting an AI build
We build and operate it. Snaplore and Talkmetry are our own revenue-generating products, running in production on GPT models and AssemblyAI, with Whisper handling speech in Snaplore, and Snaplore has active users. The client record is dated and on Clutch: a language problem inside a live accounting system in 2017, a self-improving recognition tool for a Munich software company in 2020, and QA on an AI platform we had not built in 2023.
What decides it is a scored, repeatable measure of correct, written down before the feature ships. Without one the launch decision is whether the last demo went well, and next year's model upgrade is a gamble rather than a decision. Around that sit cost controls, monitoring for drift, and AI application security covering prompt injection, data leakage and model access controls. That work is a service in its own right: AI QA and evals.
Yes, and the table above is the short version of that conversation. A process that never varies wants automation, not a model. A regulated decision wants assistance, not autonomy. A general question a hosted assistant already answers wants a subscription. We would rather lose the build than hand you a feature you cannot put in front of a customer.
The number turns on a ratio nobody can guess from the outside: how much of an AI build is data plumbing and integration, and how much is model work. That is settled by looking at your systems rather than by describing the feature, so the scoping comes first and the quote after it. The shape we can give you now: hourly on time and materials, a fixed price against a defined outcome, or a monthly rate per team member on team extension. There is no minimum engagement period, so a first piece of work can be genuinely small. Most engagements start within two to four weeks.
Yes, and that is the usual starting position rather than the awkward one. We work across hosted models and cloud AI platforms including AWS Bedrock, and we build with LangChain and Model Context Protocol where they fit. A platform decision that is already made and defensible is not worth reopening; what is worth checking first is where it will cost you later, because lock-in shows up in the migration and never in the pilot. Putting a model inside software that already carries users is its own service: AI integration.
What teams usually pair this with
All servicesPut working AI in your product
Tell us where AI is supposed to pay off in your stack, and what already runs there. You get a straight read from a company that operates its own AI products, including the version where the answer is not yet.