AI Agent Development Services for software that decides the next step, then takes it.
An AI agent is software that takes a goal, plans the steps and carries them out across your tools, deciding with a language model and acting with scoped access to your systems.
- 120+Projects delivered across 12 countries since 2012
- 100+Senior in-house engineers, six countries
- 5.0Unified rating across 61 client reviews on Clutch
- ISO 27001Certified security practice, audited by Quay Audit UK
- AWS CertifiedSolutions Architects on the team
01Overview
When is an AI agent the right thing to build?
When one repetitive job varies too much for a fixed script, and the person doing it spends the day making small judgments rather than following a rule. Coordinating several agents, tools and data sources on one workflow is what the field calls agentic AI, and Gartner predicts that over 40% of agentic AI projects will be canceled by the end of 2027, naming escalating costs, unclear business value and inadequate risk controls rather than model capability. So what we sell here is the boundary as much as the agent.
- One agent, one jobA build opens by naming the single job and writing down what done means. A general-purpose assistant is how a pilot stalls before anyone will let it act.
- Autonomy is earned, one action at a timeThe agent starts supervised. Each action it is later allowed to take alone is a decision you make on evidence, rather than a default it arrived with.
- Built to your requirementsAgents here are built to your requirements, so what one is allowed to do, tool by tool, is your specification rather than a product default.
- The rest of the AI clusterAI integration when the model belongs in a product you already run, conversational and voice AI when the interface is the conversation, and MCP for the access layer under both.
02Proof
What we have actually run
Judge us on the systems we run rather than the ones we demonstrate: an agent on our own back office, the AI layer inside meinUnterricht's product, and two AI products with active users.
- An agent we run on ourselvesOur internal AI web agent reads a text prompt, navigates unicrew's own project management system on its own, finds the people whose time logs are missing for the previous week, and notifies both them and their managers via Google Chat. It ran as a proof of concept, on AWS Bedrock and LangChain with Python underneath.30%improvement in timely work-time logging compliance on unicrew's own team
- AI inside a client's own productAt meinUnterricht we owned the work end to end, from the user-facing search features to the AI tagging and embeddings underneath them, which set up their move to vector search. An agent depends on exactly that reach: someone who can work the data layer of a product you already sell.~9%higher search success rate at meinUnterricht, measured in a controlled experiment
- Two AI products with active usersSnaplore turns meetings, calls and screen recordings into searchable documentation, and Talkmetry is call intelligence for HubSpot. Both are ours to run, which is a different relationship with a model's cost and failure modes than shipping one and leaving.2AI products of our own, revenue-generating, with active users
03Compare
Agent, chatbot or script: which one fits?
Pick an agent when the work is high volume, the inputs vary, the job crosses more than one system, and you can still say what a correct outcome is. Where the steps never change, a script is cheaper and fails more predictably. Where a person will take the action themselves, a chatbot is enough. And where the process still changes every month, settle it first: an agent pointed at an unsettled process amplifies the confusion instead of absorbing it. Volume decides whether to automate; variation decides whether it needs an agent.
| An AI agentunicrew | Scripted automation or RPAAutomate | Chatbot or assistantAssist |
|---|---|---|
| Best forHigh-volume work where the inputs vary and you can still state what a correct outcome is. | Best forSteps that are identical every time, on inputs that hold their shape. | Best forAnswers people need fast, where a person still takes the action. |
| What it asks of youEvals, guardrails and integration built alongside the agent, and a budget line for model spend after launch. | What it asks of youInputs that hold their shape, and an update to the script whenever an input format changes. | What it asks of youLittle integration work, and a person on hand to take each action the answer points to. |
| You end up owningThe agent, the eval suite that scores it, and the access layer underneath. | You end up owningA script, and the maintenance queue behind it. | You end up owningPrompts, content, and the manual step you started with. |
Quick self-check
Tick what is true for you. The read-out updates as you go.
0 of 4 true
Start with scripted automation
Steps that repeat on inputs that hold their shape are what scripted automation is for: it does the job for less and fails predictably. An agent fits once the inputs start to vary and the exception list keeps growing.
Talk it throughOne signal is a process question
One box ticked usually points to a process question first. We settle it with you, so any agent that follows works on a process that has stopped changing month to month.
Talk it throughRun a pilot before you fund a rollout
Two boxes is the case for watching an agent work your real tasks in a contained setup. The pilot shows, on your own work and at the lowest cost, whether hardening comes next.
Book a discovery callThe shape fits; the open question is authority
Three boxes and an agent is the right tool. What is left to settle is the single job it owns and how much of that job it may finish before a person looks.
Book a discovery callAn agent, with the autonomy gate designed first
All four. Here the eval and the approval rules are the first design decision rather than the closing stage, because an agent that commits actions on inputs that vary is one you cannot judge by watching a demo.
Talk about the workOn an AI agent build, governance is the first thing we design. We agree which actions the agent takes alone, which need a human sign-off, and how its decisions are logged. We also define how it handles a case it was not built for.
 Andrii BurdaSenior Engineering Manager, unicrew
04Capabilities
What we build
Seven builds. Which one you need depends less on the model than on how much authority the agent needs, and on what it has to reach to use it.
- Workflow automation agents
Workflow agents that execute multi-step tasks
One job, a definition of doneAgents that own a job end to end: read the request, plan the steps, act across the tools involved, and report what they did. Where the steps never vary, we build it as scripted automation instead, which does the same job for less.
- Agents inside your own tools
Agents embedded in your existing systems
Inside your CRM or helpdeskAn agent is only useful where the work happens, which means inside the CRM, helpdesk or internal tools you already run, with the permissions and the approval path that placement demands.
- Tool access for agents
The MCP access layer
Model Context ProtocolMCP (Model Context Protocol), the open standard Anthropic published in 2024, is how an agent reaches your data and tools without a piece of glue code per system. Building and securing the servers themselves is its own engagement.
- Agent guardrails and autonomy limits
Evals and guardrails
Scored against real tasksBefore an agent is allowed to act alone it has to be scored on your own work, and bounded for the times it gets one wrong. That gate is part of the build rather than an upsell after it. Running the scores continuously once it is live, across features that never answer the same way twice, is a separate engagement.
- Human-in-the-loop agent design
Human-in-the-loop and access design
One action at a timeAutonomy is a dial, not a switch. We design which actions the agent takes alone and which queue for a person. A data-recognition build we shipped works exactly that way: the software proposes each result, an operator signs it off or fixes it, and every fix updates the algorithm, so the machine gets better at the part the person keeps correcting.
- Conversational and voice agents
Voice and conversational agents
Speech, turn-taking, handoverWhen the job is a conversation that ends in an action (booking, triage, qualification), the agent needs speech, turn-taking and a handover that does not lose context.
- Internal operations automation
Internal-operations agents
Consequences stay insideChasing compliance, reconciling records, triaging tickets. Often the safest first agent, because a mistake stays inside the building and you can watch it work. We run one of these on ourselves.
05Trust
What you get from an agent build
An agent build hands over a job with a boundary drawn around it, a way to score whether the agent does that job well enough to be left alone, and a written record of what it may touch, tool by tool.
- One jobAn agent with a written definition of doneThe boundary is the deliverable: what it owns, and what it hands back to a person
- Yours to rerunAn eval suite scored on your own tasksHanded over with the failure-mode list, so autonomy is earned rather than assumed
- ScopedAccess written down, per toolWhat the agent may read and what it may commit, under our ISO 27001:2022 certified practice
06Stack
The stack we build agents on
What an agent runs on matters less than what it can reach. Ours runs on AWS Bedrock and LangChain with Python underneath, and the model is an engineering choice made per case rather than a default we carry in.
 Python
- REST API
 AWS Bedrock
 LangChain
 OpenAI / ChatGPT
07Engagement
How you engage us on an agent build
All three begin by scoping the one job. What differs is what you buy first: evidence, a team, or a decision. We recommend the pilot first, because it answers the biggest question on your own work at the lowest cost: whether this job is ready for an agent.
A scoped pilot first
Start hereOne job, your real tasks, a contained setup. You watch an agent work on the actual job before funding evals, hardening and rollout, so the next step is decided on evidence.
- Best when
- One job is already the obvious candidate and you want proof before a budget
- You pay
- Outcome based, quoted per project
- Typical start
- Two to four weeks
A dedicated team
Long-runA team that ships the first agent and is still there for the fourth. The systems an agent reaches keep changing underneath it, and every one of those changes is somebody's job the week it happens.
- Best when
- More jobs are coming and one team should be answerable for all of them
- You pay
- Billed monthly, per team member
- Typical start
- Two to four weeks
Advisory before you build
Decision firstHere the first deliverable is a decision rather than code: which jobs qualify, what your data can support, and what has to be governed before anything is allowed to act.
- Best when
- You have several candidate use cases and no agreed way to rank them
- You pay
- Billed hourly, quoted per project
- Typical start
- Two to four weeks
Score it before you decide whether to keep it
MIT Media Lab's State of AI in Business 2025 report found that 95% of corporate generative AI initiatives show zero measurable return, and only about 5% of pilots reach production with any measurable value. So the first thing we do with an agent somebody else built is run it against your real tasks and score what comes back. That verdict arrives in writing, as promote, harden or stop. Taking the rebuild to us afterwards is a second decision, made after you have read the first one. There is no minimum engagement period.
08Industries
Industries we build agents for
What an agent can do in a sector is decided by what its systems will let anything do. Below is where we have already shipped software and AI, and what an agent meets there.
Logistics and transportation
Ordering, warehousing and fleet operations that cannot be paused while software learns on them. We built a vehicle inspection platform for one of the biggest US logistics providers, field app included, so we know what an order or a load looks like before an agent is asked to touch one.
Hospitality and leisure
A booking is a promise to a guest, so an agent that changes one has consequences a support ticket does not. We have wired PMS, booking and payment platforms together, including a platform for the entertainment industry, which is where the approval line usually has to sit.
EdTech and learning
The useful agent here reads a large content library rather than a database of rows. We embedded an engineer on an EdTech platform's search team and built the AI tagging and embeddings beneath it, which is the layer an agent queries rather than the interface it drives.
Fintech and accounting
High volume, rule-adjacent, and unforgiving about who was allowed to do what. We automated the bookkeeping for a UK financial advisory firm, where the hard part was software reading transaction descriptions written in prose and acting on them. That is the shape of work an agent is genuinely good at.
Healthcare
The blast radius is a patient, so autonomy starts near zero and is argued upward one action at a time. We are the long-term technology partner behind a home health monitoring platform and have integrated additional third-party data sources into it, which is where those arguments get had.
E-commerce
An agent here works the whole chain or it works nothing: the storefront, the ERP behind it, and each marketplace on the side. For a European manufacturer selling in seven EU countries our developers worked on the middleware joining Shopify storefronts to a Microsoft Dynamics ERP for a catalogue of more than 10,000 products, which is the chain an agent would have to work.
Which job would you let an agent own first?
Bring that one job. What comes back is the right build for it, an agent or a scripted automation, and what it would take to reach the systems and actions it touches.
What happens after you contact us
- We reply within one business dayThe reply says whether the job you described sounds like one an agent should own, and what we would need to see to be sure.
- A call about the one job, not the modelWhich job, what it would read, what it would be allowed to do without asking, and who signs off on the actions that carry consequences.
- A written agent briefThe single job, the systems it has to reach, the actions that need a person, and what done means.
- Contracts and NDAs, then a start dateSigned before anything of ours reaches your systems. Most engagements start within two to four weeks.
09Delivery
How does an AI agent build run?
Five stages: scope the job, open the systems, pilot, gate, run. The pilot is the one that decides everything after it, because the evidence for every later stage comes off your own work. Every stage names what we need from your side, because that is where the time actually goes.
- Scope the job the agent ownsOne job with measurable value and a written definition of done, settled before any code. From you we need the people who do the job today, because they know the exceptions nobody documented.You getA written agent brief: the one job, the tools it may use, the actions that need a person, and what done means.
- Map and open the systems it has to reachWe inventory what the agent needs to read and which actions deserve to be tools at all, then wire them. From you we need the API documentation and somebody who is allowed to open a test environment without a change board meeting.You getAn access map, and a working connection to each system with per-tool scopes written down.
- Pilot against real tasksThe agent runs against your real tasks in a contained setup, so you judge completion rate and failure modes on actual work rather than a demo script. From you we need a slice of those tasks in the messy state they arrive in, and somebody who can say whether an answer is right.You getA completion rate and a failure-mode list measured on your own work, plus a go or no-go recommendation.
- Gate with evals and guardrailsAn eval suite scores the agent against real tasks, and guardrails bound what it can do when it is wrong. Consequential actions route to a person until the evals earn them autonomy. From you we need whoever owns each of those actions, because where the line sits is their decision rather than ours.You getAn eval suite you can rerun, a guardrail and approval policy, and a written autonomy level for every action.
- Run with monitoring and cost controlsThe agent runs with monitoring, drift checks and cost controls. Model and infrastructure usage keeps running after launch, so it gets a budget and an owner rather than a surprise invoice. From you we need that named owner, and a budget line the usage can sit against.You getMonitoring and drift checks, a token and infrastructure cost budget, and a named owner for changes.
10Client voices
What clients say
Our headline result was a controlled experiment showing a roughly 9 percent lift in search success rate. The features built are live in production, and the AI tagging and embeddings work set up our move to vector search. What stands out most is their ability to own work end to end, from user-facing search features to the AI and data layer underneath.
Even though Artelogic didn’t have a background in this area, they learned quickly and repurposed technologies they’d used before in order to solve the business problem. I was very impressed with this ability, as most of the people we contacted before implied that they’d need to spend a lot of time of trying to understand our business logic.
Shippable and well received web GUI for previously API only application. The whole team is highly dedicated to the success of the project and delivers the planned artefacts on time. We are very happy to have chosen Artelogic.
Artelogic’s work had a very positive impact on our team’s morale. As our development quality was improving, our engineers were more confident in what they were doing, allowing them to work faster and with more confidence. As a result, our releases took less time and were less stressful.
They always seem to have a suitable developer on standby when we require an additional skillset and they always respond very quickly and help to work out a solution if e.g. the project requirements are suddenly changing.
11Case studies
AI and agents we have shipped
Two of our own: the agent that chases missing timesheets across unicrew's own project management system, which ran as a proof of concept, and Snaplore, the AI product we sell. unicrew has been building software since 2012, under the Artelogic brand until the rebrand, which is the name in three of the quotations above.
See all case studies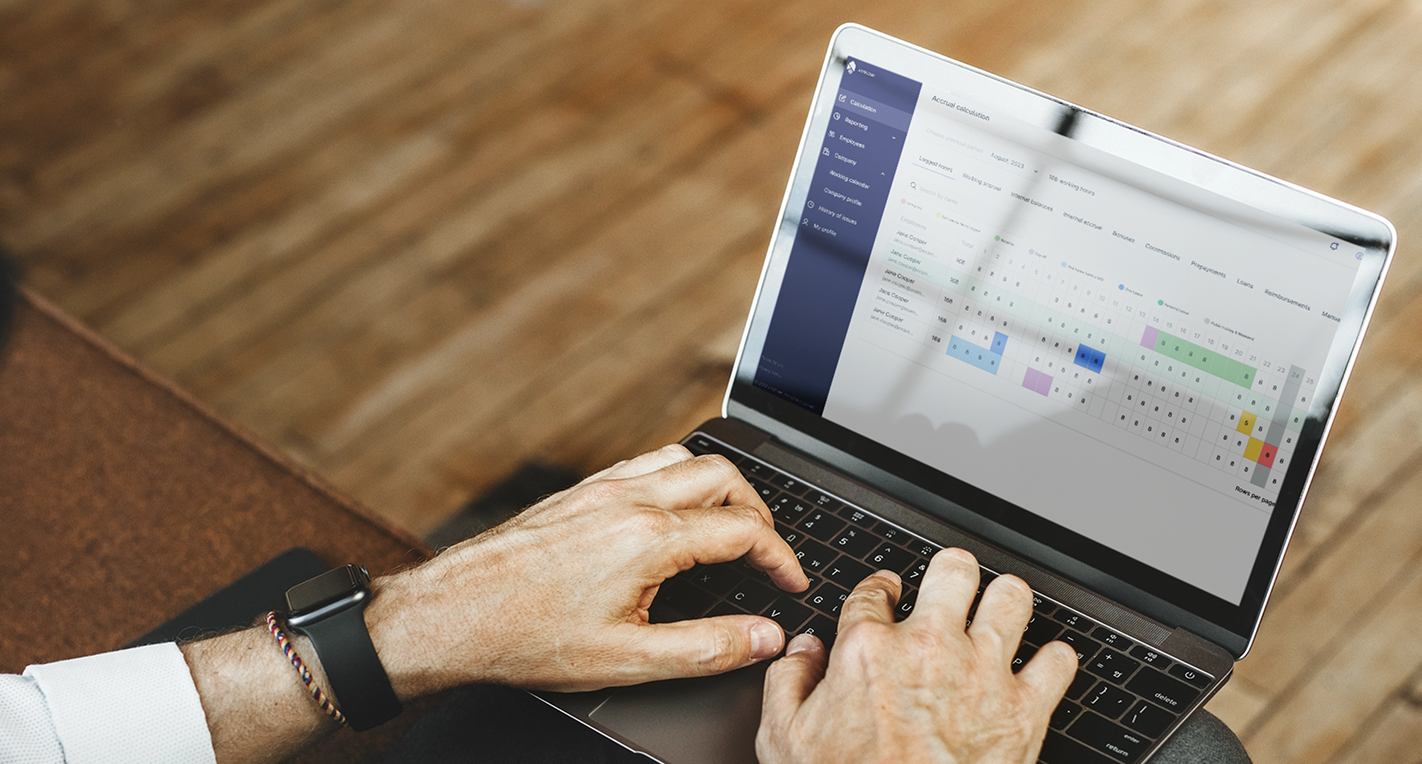 Built by unicrewAI-Powered Automation for Project ManagementAn AI bot that enhances operational efficiency by automating a critical, time-consuming, internal administrative task.30%Improvement in timely work-time logging compliance
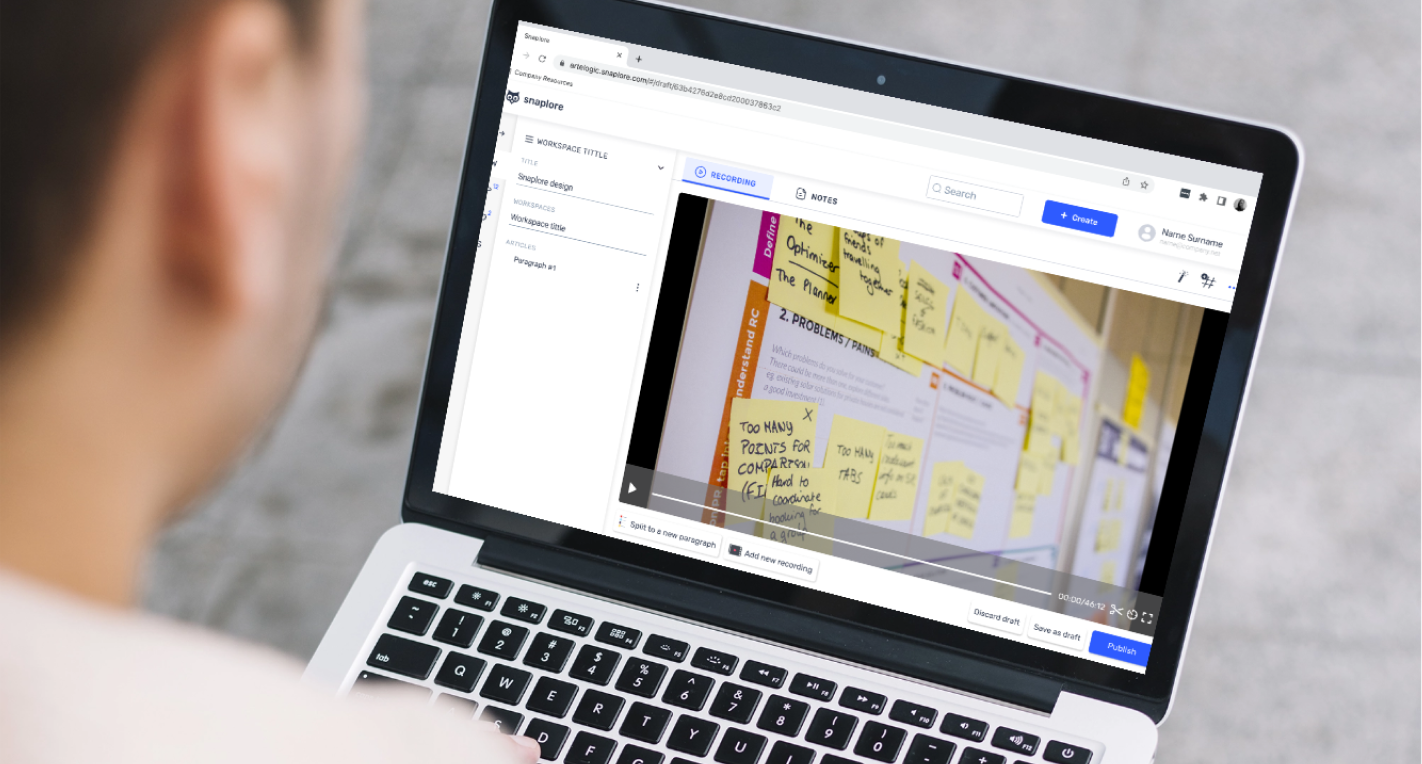 Built by unicrewRevolutionizing Knowledge Management powered with AISnaplore is unicrew's own product, built and operated in-house. It uses AI to transform how organizations document, structure, and share information, making meetings, training, and project discussions instantly accessible and actionable.Up to 60%Less time on documentation
12Questions
About AI agent development
Two variables run through most of these answers: how many systems the agent has to reach, and how settled the process is before it starts.
An AI agent uses a language model to decide which steps to take toward a goal, then carries them out with tools, instead of following a fixed script. RPA and scripts follow a pre-scripted sequence, so they break the moment the interface changes or a case turns up that the script did not anticipate; an agent plans its own sequence from the current state and can adjust when something unexpected happens. That flexibility is the catch as well: the same input can produce different behavior, which is why an agent needs evaluation and guardrails where a script needs neither. One agent handles one well-defined task. Agentic AI is the wider system that coordinates several agents, tools and data sources to complete a multi-step workflow on its own.
Four things set it, and all four are yours rather than ours: how many systems the agent must reach and how clean that access is, how consequential its actions are (which is what sets the eval, guardrail and approval work), how much data preparation the job needs first, and whether we run it after launch. We quote against your scope once those are known. Budget for the running cost as well, because model and infrastructure usage does not stop at go-live, which is the line most agent budgets miss. Where you would rather fund a team than a project, a dedicated team is billed monthly per team member.
What decides how fast a pilot moves is on your side: how quickly the single job can be agreed and the tasks it will run against can be reached. Our own guide to AI agents for business puts numbers on what follows: a well-scoped single-process deployment with clean data can reach production in roughly 6 to 10 weeks, while multi-system deployments with significant data preparation typically run 3 to 6 months. The agent is rarely the long pole. Mapping the process it is meant to own usually is.
Yes, and an agent that cannot reach your systems is just a chatbot. MCP (Model Context Protocol) is the open standard for that reach, and building and securing the servers behind it is an engagement of its own. Where there is no clean API the agent can drive the interface instead, which is what our own does inside a browser, and running it is why we take an API wherever one exists: anything driven through a front end inherits that front end's habit of moving. A decade of wiring PMS, ERP, payment and booking platforms together is the part of this work that predates agents entirely.
Three things: an evaluation suite that scores the agent against real tasks, guardrails that bound what it can do when it is wrong, and access scoped so it can only touch what its job requires. On top of those, human approval for consequential actions, monitoring and cost controls, and access designed under our ISO 27001:2022 and ISO 9001:2015 certifications, audited by Quay Audit UK.
AWS Bedrock and LangChain for the runtime, with Python and browser-automation libraries underneath. That is the stack behind our own internal agent, so the recommendation comes from operating one rather than from a partner brochure. Model choice is an engineering decision we make per case: we publish where an Anthropic Claude model is the right choice and where it is not, and the same question gets asked of every other model on the shortlist.
Compare one level below the category, where three checks work from outside the room. First, what a team has run rather than demonstrated, failure modes included: a demo is a curated path, and ours are documented in the case study for our own agent, down to multi-factor sign-in and the front-end selectors it works through. Second, who does the work, because in month six, when a prompt needs retuning, the person who wrote it should still be reachable: unicrew has 100+ senior in-house engineers across six countries, and the engineering happens in Ukraine, Poland, Estonia and the UK. Third, the reviews themselves: the 5.0 rating on this page rests on 61 client reviews on Clutch, and every client quoted here links to their full interview, which is where the useful detail sits.
The agents we have run end to end are our own. One works a browser-based admin job across unicrew's own team and ran as a proof of concept; two AI products we own and sell run in production with active users. For clients we have built the AI layer inside their products, including the tagging and embeddings behind an EdTech platform's search, and the automation and integration work an agent depends on to reach anything. Your agent build draws on both: the agent pattern we run on our own operations, and the reach into client systems we already deliver on theirs.
When one named job crosses several systems, the inputs vary, the process has settled, and someone can state what a correct outcome looks like. Where the data it needs is not yet reachable, data engineering comes first in the plan, so the agent has reliable data to read. Where the job turns on judgment, relationships or organizational context, the agent surfaces the data and drafts the options, and a person owns the workflow. And the agent owns one job with a written definition of done, because a focused job is how a pilot earns its promotion to production.