Data engineering, integration and automation, and which one your problem needs first
Data and platform services are three jobs that arrive looking like one: making the data trustworthy, making the systems agree, and taking the manual steps out from between them. Which one you buy first is what this page decides.
01Work
Four symptoms, and the cause under each one
These four arrive looking alike and have three different causes between them. The cause is what decides which of the three services is yours.
The month-end spreadsheet nobody will delete
Someone assembles it by hand because no system can produce it, and the rules for calculating it now live in that file and in one person's head. Two things are missing at once: a reporting layer that can answer the question, and a written definition of the answer.
A person carrying work between two systems
The systems hold the record and somebody moves it between them by hand, so the throughput and the error rate are a person's. Which service fixes it turns on one question: can those systems reach each other at all? If they cannot, the connection has to be built first, and that is integration. If they can, and the steps are still done by hand, that is business process automation. Both shapes turn up in our e-commerce and logistics work.
Reports that take a week and are stale on arrival
A better dashboard on top of pipelines that arrive late buys a faster picture of last week. The lag is in how the data gets there rather than in what draws the chart, so a tooling purchase leaves it exactly where it was.
An AI feature that returns the wrong document
Retrieval only works over data that is clean, current and governed, and no model choice compensates for a search layer that cannot find the right document. It presents as a model problem, and what it stalls is the AI build waiting behind it.
02Services
Three services, and which one goes first
One row per service page. The three overlap in symptom and separate on cause, so the trigger, rather than the description, is what tells you which page is yours.
| Service | What you are actually buying |
|---|---|
| Data engineering | The numbers are not trustedPipelines, warehouses, lakes and the governance that makes a figure defensible, for when the systems already talk and nobody believes what comes out. Analytics and AI both inherit whatever this layer gets wrong. On a German edtech platform's search we built the tagging and embeddings underneath while the user-facing features shipped on top; the client's headline result was a controlled experiment showing a roughly 9 percent lift in search success rate.Data engineeringOr book a meeting |
| Platform development and integration | Systems cannot reach each otherConnecting the systems that produce and consume the data, so a record entered once appears everywhere it should. A food production group's EDI tool is this shape of work: it collects that group's clients' orders, and the client says it generates significant daily revenue.Platform development and integrationOr book a meeting |
| Business process automation | People move the work by handThe workflow itself turned into software, for when the systems can already be reached and a person is still carrying the work between them. At a Munich software company, two people typing data into the database got through about 5,000 new data sets per month; with the component unicrew built, the client says they are reaching twice that.Business process automationOr book a meeting |
03Fit
Where a warehouse pays off, and what comes first
Each of these six situations has a right first step. Some start with a definition agreed on paper or a narrower build than the platform on the quote; the last two are where the data layer is the right first purchase.
| Your situation | What we recommend |
|---|---|
| One source system, a few million rows, and slow reports | Replica and indexesA read replica and some indexing make the reports fast now. A warehouse earns its place when the second source system arrives, and that is the point to build one. |
| Reports disagree, and nobody can say which definition is correct | Definitions firstTwo teams mean different things by "active customer". No pipeline resolves a definitional disagreement; it just computes both faster. Agree the definitions on paper first, then we build to them. |
| A vendor has quoted a platform migration to unlock AI | Scope it downA first AI use case needs a handful of well-governed tables, not the whole estate moved. Start with the data that use case actually touches. Moving everything first delays the thing that justified the move, and the estate is no easier to move later. |
| A workflow that changes shape every few weeks | Automate what is stableAutomation fixes a process in code, so it pays off on the steps that hold still. Start with the stable parts and add the rest as it settles, rather than rebuilding it each time it moves. |
| Data spread across systems, and an AI project waiting on it | Start hereThis is the case where the data layer is unambiguously the right first purchase, because the AI work behind it can only be as good as what it reads. Data engineering, then the model. |
| Manual re-keying between systems that cannot reach each other | IntegrateThe clearest return in this category, because the current cost is a measurable number of hours. Integration against the systems as they are, with no replacement programme attached. Where they can already reach each other and a person is still running the steps, nothing needs connecting and the answer is automation. |
How we work
We build on AWS, Azure and Google Cloud, to whichever of them you already run. We are certified to ISO 27001:2022 for information security and to ISO 9001:2015 for quality management, both audited by Quay Audit UK. ISTQB-certified QA sits inside every sprint, on every engagement. Most engagements start within two to four weeks.
04Order
The order we work in, and why it starts this small
Four steps, deliberately narrow. The failure mode in this category is scope, not difficulty.
- Pick one question the business cannot currently answerNot a data strategy. One question somebody wants answered on a Monday, with a name attached to it. Everything else is scoped against that question, which is what keeps the first delivery small enough to be checked.You getOne named question, one owner
- Trace it back to where the data is actually bornExpect more systems than anyone remembers, and at least one spreadsheet. The map is the deliverable: every hop from where a figure is created to the report it lands in, written down and still useful after the first question is answered.You getA written data-flow map
- Build the narrow pipeline, and prove the numberOnly the tables that question needs, landed, cleaned and documented, with the answer reconciled against however the business calculates it today. If they disagree, that is the finding.You getA reconciled figure, and its lineage
- Widen only where a second question pullsEach further question extends the model rather than restarting it. Building the warehouse first and looking for the questions afterwards is how this work becomes a programme nobody can cancel.You getAn extension, not a rebuild
We start data work with the one question the business needs answered every Monday morning. Answering it usually takes a few well-built tables. The platform then grows one question at a time, and each step gives the business a report it can trust.
 Yaroslav HavrylivSenior Engineering Manager, unicrew
05Proof
Where the data layer moved a number the client tracks
- AutomationDoubling data-entry throughput with a custom recognition toolunicrew automated a manual data-entry bottleneck with a C# and AWS recognition tool, doubling the data sets the team got through each month.2xData sets processed per month
- EducationThe custom time-tracking tool that got around 40% more project leaders tracking time at RWTH Aachen Universityunicrew built a custom time-tracking web app for a research group at RWTH Aachen University, in place of spreadsheets or off-the-shelf software.~40%More project leaders tracking time
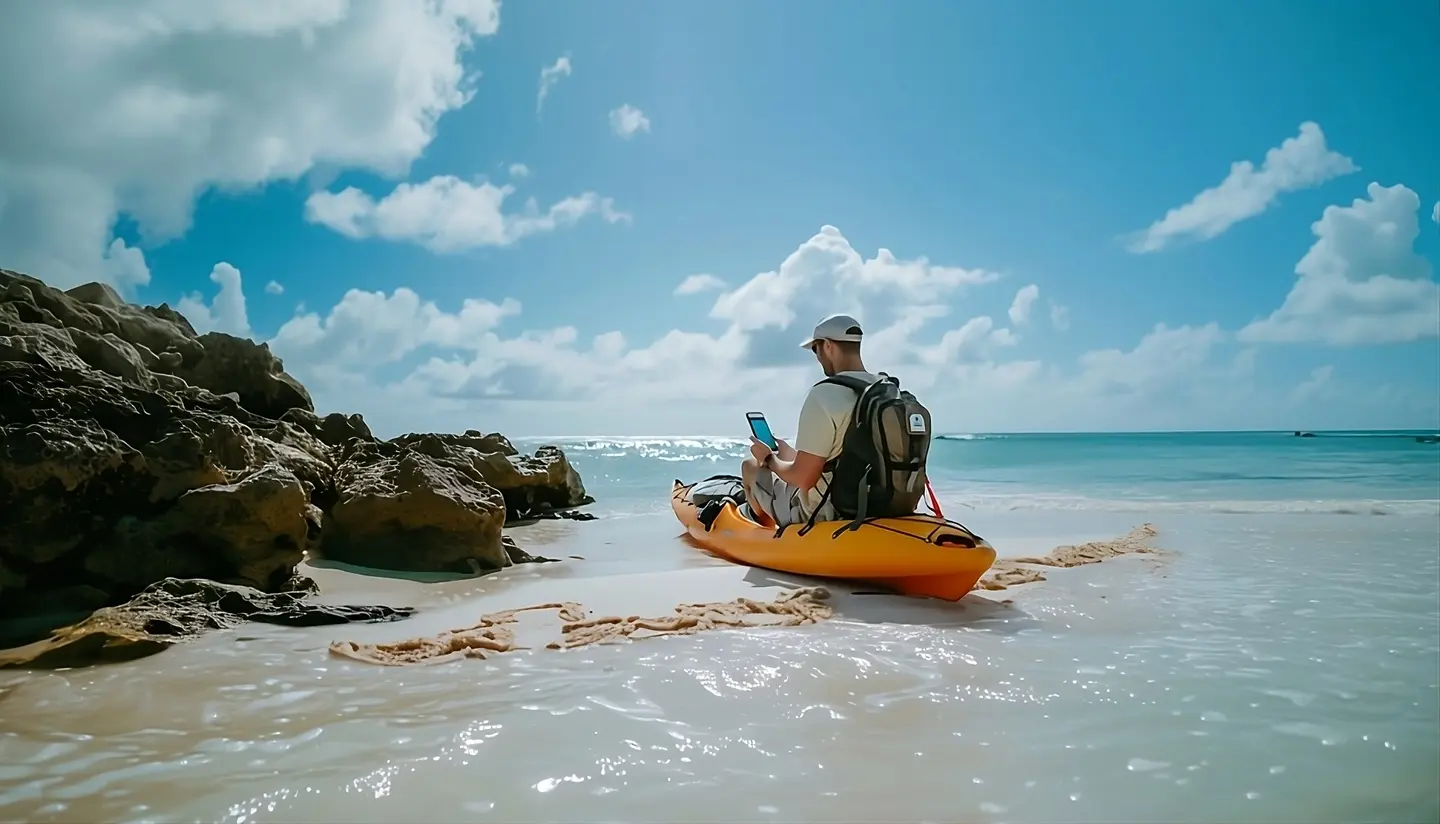 LeisureSaaS modernization for Paddle Sports Center in CaliforniaA kayaking and paddleboard rental business in the Santa Barbara area wanted one system for equipment, customers, time and billing. That system is Adventure Rental System.15-20%Increase in revenue
06Clients
Five clients on what the data and platform work changed
Two people typing data into the database went about 5,000 new data sets per month. With this component, we’re reaching twice the amount of data sets per month. Their knowledge of different technologies is astounding. We can raise any technical issue with them and find someone within their team to work with that specific technology.
We’ve seen a 15-20% increase in revenue, which is through the efficiency gains and the ability to accurately track time on a permanent basis rather than just by a quarter hour or an hour. I’ve worked with a lot of development teams over the years and these guys have been the best. It’s nice to finally find a team that we can work with.
We saw around a 40% increase of how many project leaders are tracking the time of their employees instead of making guesses or delegating the task. Their response time was fantastic. They were organized and provided us with tools to track their progress in a transparent way. Every time we needed to add some small things to make it work better, they adapted those requirements very quickly.
Our headline result was a controlled experiment showing a roughly 9 percent lift in search success rate. The features built are live in production, and the AI tagging and embeddings work set up our move to vector search. What stands out most is their ability to own work end to end, from user-facing search features to the AI and data layer underneath.
Artelogic invested time to understand our needs and has subsequently proposed appropriate solutions. In the end, the team’s quality deliverables have created value for cost. The EDI tool generates significant daily revenue and helps us solve order collection issues.
07Questions
What teams ask before starting data work
Three services, and one question decides which is yours. Data engineering is for when the systems already talk and nobody believes the numbers coming out of them. Platform development and integration is for when the systems cannot reach each other at all. Business process automation is for when they can, and a person is still carrying the work between them. Where two of the three apply, start with the one the others are waiting on.
Because AI fails quietly on bad data rather than loudly. Retrieval systems and agents return the wrong thing, or write confidently around a gap, and the symptom looks like a model problem. Whatever a model can answer is bounded by what the layer underneath it can find: clean pipelines, systems that agree on a record, and data somebody governs. That work is also the narrower piece, because it is scoped to the tables the first use case actually touches rather than to the estate.
Yes, and they are the clients' own figures on Clutch. At a Munich software company, two people typing data into the database got through about 5,000 new data sets per month; with the component unicrew built, the client says they are reaching twice that. A German university's time-tracking tool produced around a 40% increase in how many project leaders track their team's time instead of guessing or delegating it. unicrew handles a food production group's EDI tool, and that client says it generates significant daily revenue and helps them solve order collection issues.
Yes. We build on AWS, Azure and Google Cloud, and the work goes onto whichever of them you already run rather than onto a migration you did not ask for. Where your current setup makes the thing you asked for genuinely impossible, we will say so and write down the reasoning, so you can disagree with it before anything is committed.
Most engagements start within two to four weeks, and there is no minimum engagement period. Billing is hourly time and materials, a fixed price against an agreed outcome, or a monthly rate per person for a standing team. One scoped question suits a fixed price; open-ended pipeline, platform or automation work is better on time and materials or a standing team. What comes back first is an answer to that one question rather than a platform, so if a proposal in this category quotes a year before anything is usable, that is a scoping decision rather than a technical necessity.
What teams usually pair this with
All servicesWhich number do you not trust?
Name one report, one workflow or one AI feature that is not working, and we will trace it back to where the data goes wrong. That trace becomes the plan for the fix.